
生命是一场放逐和流浪。
Life is an exile, a wandering.
只是大部分人都将自己交予了俗世,用别人和社会既定的轨道牵绊自己前行。
Most people give themselves over to the ordinary, bound by the scripts society has written for them.
而内心的声音,早在懂得谄媚于人之前就消失殆尽;又或者,永远在耳畔孤独地回响。
The inner voice dies long before they learn to compromise, or it survives only as a lonely echo.
有些人能清楚听见自己心灵的声音,并按这个声音生活。
Some people hear their own inner voices with great clearness. And they live by what they hear.
这样的人,不是疯了,就是成了传说。
Such people become crazy ... or they become legend.
SOFTWARE SYSTEMS · HARDWARE · RESEARCH
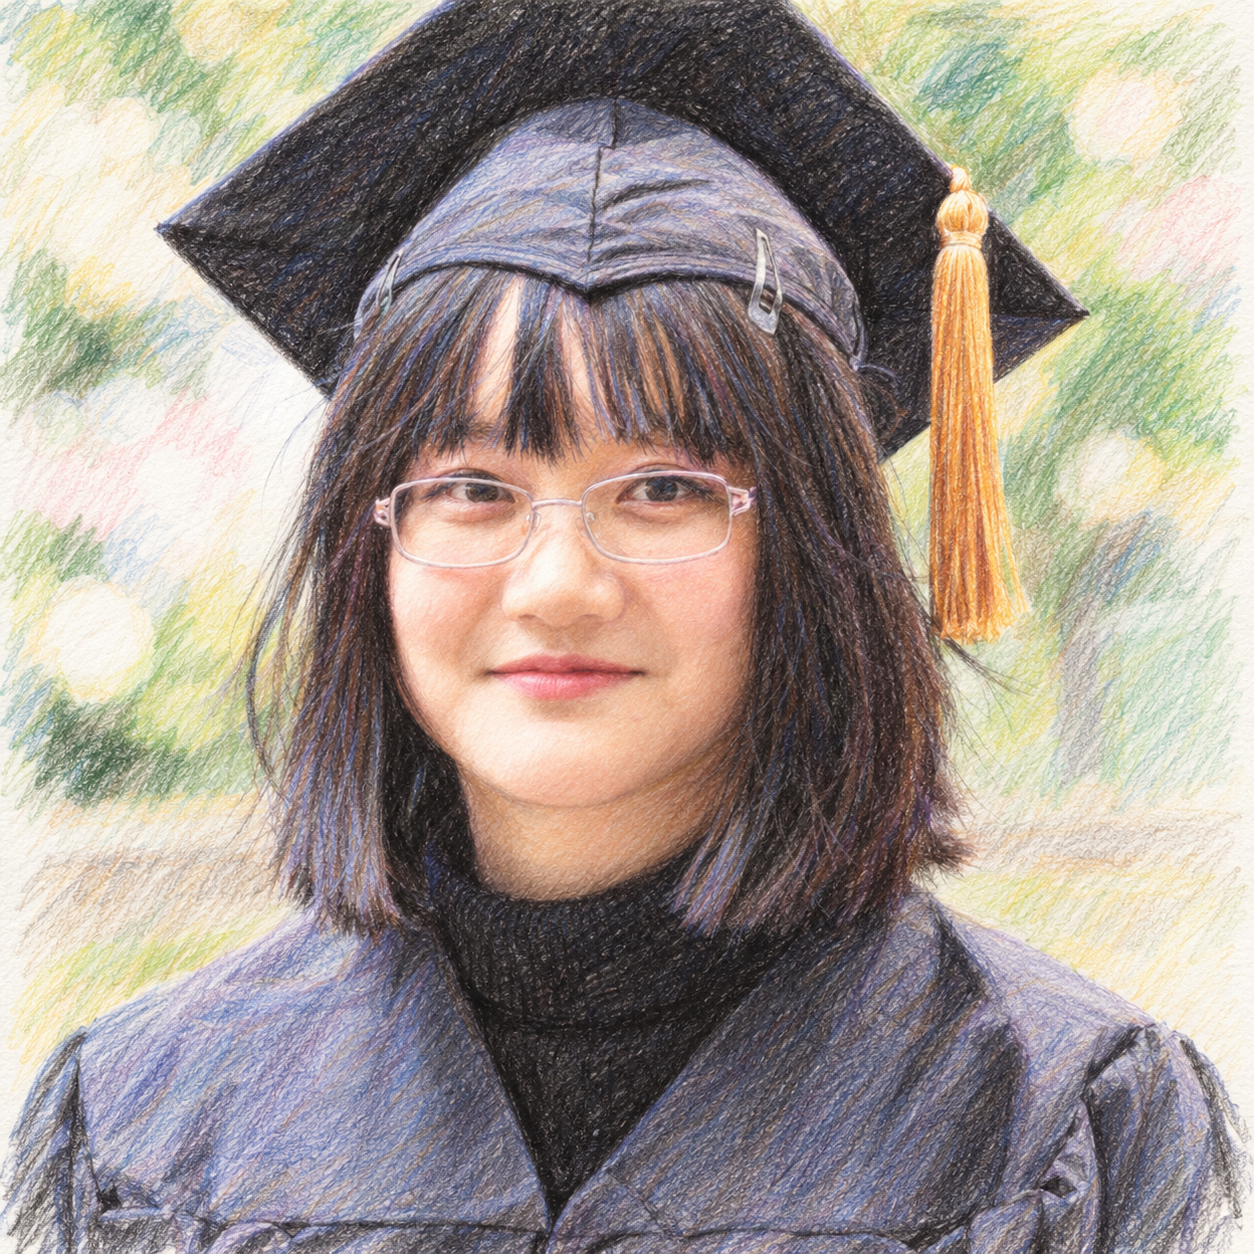
Yuxuan Zhang
Bridging data center applications and server processors.
Software Engineer @ Google · PhD, University of Pennsylvania
I received my PhD from the Computer & Information Science Department at the University of Pennsylvania. My advisor is Prof. Sebastian Angel, and my former advisor is Prof. Joseph Devietti.
- OS
- Compilers
- Computer Architecture
- Serverless
- gRPC
- Distributed Systems
- VLSI
Education
-
University of Pennsylvania
PhD in Computer Science · GPA: 4.0
Philadelphia, PA. 08.2019 - 12.2025
PhD Thesis: Leveraging Feedback for Dynamic Execution Optimization -
 University of Michigan, Ann Arbor
MS in Electrical Engineering
Ann Arbor, Michigan. 08.2015 - 12.2017-
Two-way superscalar R10K Out-of-Order processor
- Implemented 2-way associate non-blocking writeback data cache and its cache controller which maintains outstanding cache misses status.
- Implemented key components such as Reservation Station, hardware register map table, Reorder Buffer, Load Store Queue of the OoO processor.
- Modified visual debugging tools and re-design the testbench to support performance analysis of the OoO processor.
-
Design and Verify a Cache Coherency Protocol
- Designed and verified an invalidation based MOESI self-downgrade cache coherence protocol for the multicore memory system by enumerative model checker Murphi.
-
Wikipedia Search Engine
- Built a scalable search engine which supports information retrieval based on both tf-idf and PageRank scores.
- Indexed webpages with Hadoop MapReduce framework to scale to large corpus sizes.
- Built a new search engine interface with two special features: user-driven scoring and summarization.
-
Two-way superscalar R10K Out-of-Order processor
 Harbin Institute of Technology
BS in Electrical Engineering
Harbin, China. 08.2008 - 07.2012
Undergraduate Thesis: VLSI Architecture Design of 2-D Discrete Wavelet Transform in JPEG2000 Encoder
Employment
-
 Software Engineer, Google LLC
RPC (stubby+gRPC) Team, Sunnyvale, CA, 01.2026 - Present- gRPC Mitigation Engine
- Built continuous integration and automated end-to-end testing infrastructure for the gRPC Mitigation Engine, enabling production rule deployment through Fireaxe and Chubby and improving protection against DDoS and Query-of-Death (QoD) attacks.
- Built a microbenchmark to quantify the performance overhead introduced by the gRPC Mitigation Engine, measuring its impact on server latency, CPU/GCU usage, and memory consumption.
- Designed and implemented a unit-testing framework with an easy-to-use API for mitigation authors to validate rule correctness and behavior before production deployment.
- Developed a fuzz-testing framework that generates randomized mitigation rules and gRPC requests to uncover server crashes and robustness issues, while providing reusable fuzzing interfaces for mitigation authors to stress-test their own rules.
- gRPC C++ Connection Throughput Microbenchmark Monitoring
- Built a gRPC C++ connection-throughput microbenchmark to measure key performance metrics, including latency, GCU usage, and memory consumption.
- Integrated the benchmark into the performance testing pipeline for nightly monitoring and presubmit checks, enabling early detection and prevention of performance regressions.
- gRPC in Prod xDS ORCA-to-LRS Propagation Test
- Implement querying Monarch programmatically for GSLB (Global Service Load Balancer) load reports and named query cost/utilization to verify if it aligns with the metrics reported in the gRPC clients in C++, Java and Go.
- Stubby PSP SADB Channel Eviction
- Implement logic to evict Stubby C++ client and server channels when the SADB (Security Association Database, hardware-level database designed to manage encryption keys for NIC) reaches capacity, causing encryption to transition from hardware encryption to LOAS (Low Overhead Authentication Service) software encryption.
- Cross-Language gRPC/Stubby ExtProc Interop Test Framework
- Implemented a cross-language gRPC/Stubby interoperability testing framework using Guitar (Google Unified Integration Testing and Releasing) to validate correct interactions between gRPC filters and external processors (ExtProc)
-
Software Engineer Intern, Google LLC
Data-systems Efficiency & Codesign Team, Sunnyvale, CA, 05.2025 - 08.2025- AI Agent for BigQuery Benchmark Generation
- Analyze performance bottlenecks in Google’s production workloads via profile collected by Google-Wide Profiling (GWP).
- Use LLM tool AlphaEvolve to generate synthetic workloads which yields the same performance metrics as production workloads
-
 Software Engineer Intern, VMware LLC
Monitor Team, Boston, MA, 05.2022 - 08.2022- Prevalidation during Pre-copy of memory pages
- Offloaded the pre-validation of the destination VM’s page table from Virtual Machine Monitor(VMM) to ESXi (VMKernel, the hypervisor) after a VM is migrated from source to destination (VMotion), in order to reduce the contention of updating page tables on different VMs.
- Built prevalidation during the pre-copy of memory pages in VMotion to reduce the time spending on pre-validation.
-
 Research Intern, Microsoft Research Asia
Network Research Group, Beijing, China, 01.2018 - 07.2019- GLane on GPU
- Built a Linux module that can expose an NVIDIA GPU’s physical memory for direct data transfer, and a hardware stack for GPUs in a device-centric cluster to buffer and transfer data.
- Prototyped CUDA code to perform GPU computation and data transfer in parallel without host CPU involvement.
-
 Software Engineer Intern, Nvidia Corp.
High Performance Computing team, Beijing, China, 05.2017 - 09.2017- Input Batching for TensorRT
- Developed a CPU-side input batching framework for TensorRT to optimize data flow for deep learning inference workloads.
- Implemented dynamic dispatching logic that buffers inputs until a specific throughput threshold is met, ensuring optimal batch sizes before GPU transfer.
- Enhanced overall GPU throughput by reducing the frequency of host-to-device memory copies and optimizing processing efficiency.
Publications
-
Quilt: Resource-aware Merging of Serverless Workflows
paper code slides
, S. Angel
Proc. ACM Symposium on Operating Systems Principles (SOSP), Oct. 2025This paper describes Quilt, a serverless optimizer that automatically merges workflows that consist of many functions (possibly in different languages) into one process thereby avoiding high invocation latency, communication overhead, and long chains of cold starts. Instead of merging all functions, Quilt takes into account the provider’s resource constraints to decide which functions to merge. Quilt is compatible with existing platforms without modification (Fission, OpenWhisk, and OpenFaaS), can merge functions in different languages (C, C++, Swift, Go, Rust) by acting at the level of LLVM IR, and requires no input or help from developers. Our evaluation shows that Quilt improves median workflow completion time by 45.63%–70.95% and throughput by 2.05×–12.87×.
-
RPG2: Robust Profile-Guided Runtime Prefetch Generation
paper code slides poster
, N. Sobotka, S. Park, S. Jamilan, T. A. Khan, B. Kasikci, G. Pokam, H. Litz, J. Devietti
Proc. International Conf. on Architectural Support for Programming Languages and Operating Systems (ASPLOS), May. 2024.Data cache prefetching is a well-established optimization to overcome the limits of the cache hierarchy and keep the processor pipeline fed with data. In principle, accurate, well-timed prefetches can sidestep the majority of cache misses and dramatically improve performance. In practice, however, it is challenging to identify which data to prefetch and when to do so. In particular, data can be easily requested too early, causing eviction of useful data from the cache, or requested too late, failing to avoid cache misses. Competition for limited off-chip memory bandwidth must also be balanced between prefetches and a program’s regular “demand” accesses. Due to these challenges, prefetching can both help and hurt performance, and the outcome can depend on program structure, decisions about what to prefetch and when to do it, and, as we demonstrate in a series of experiments, program input, processor microarchitecture, and their interaction as well.
To try to meet these challenges, we have designed the RPG2 system for online prefetch injection and tuning. RPG2 is a pure-software system that operates on running C/C++ programs, profiling them, injecting prefetch instructions, and then tuning those prefetches to maximize performance. Across dozens of inputs, we find that RPG2 can provide speedups of up to 2.15×, comparable to the best profile-guided prefetching compilers, but can also respond when prefetching ends up being harmful and roll back to the original code – something that static compilers cannot. RPG2 improves prefetching robustness by preserving its performance benefits, while avoiding slowdowns.
-
Online COde Layout OptimizationS via Ocolos
paper
, T. A. Khan, G. Pokam, B. Kasikci, H. Litz, J. Devietti.
IEEE Micro "Top Picks From the 2022 Computer Architecture Conferences", May. 2023.The processor front end has become an increasingly important bottleneck in recent years due to growing application code footprints, particularly in data centers. Profile-guided optimizations performed by compilers represent a promising approach, as they rearrange code to maximize instruction cache locality and branch prediction efficiency along a relatively small number of hot code paths. However, these optimizations require continuous profiling and rebuilding of applications to ensure that the code layout matches the collected profiles. In this article, we propose Online COde Layout OptimizationS (OCOLOS), the first online code layout optimization system for unmodified applications written in unmanaged languages. OCOLOS allows profile-guided optimization to be performed on a running process instead of being performed offline and requiring the application to be relaunched. Our experiments show that OCOLOS can accelerate MySQL by up to 41%.
-
OCOLOS: Online COde Layout OptimizationS
paper code slides
, T. A. Khan, G. Pokam, B. Kasikci, H. Litz, J. Devietti.
Proc. International Symposium on Microarchitecture (MICRO), Oct. 2022.The processor front-end has become an increasingly important bottleneck in recent years due to growing application code footprints, particularly in data centers. First-level instruction caches and branch prediction engines have not been able to keep up with this code growth, leading to more front-end stalls and lower Instructions Per Cycle (IPC). Profile-guided optimizations performed by compilers represent a promising approach, as they rearrange code to maximize instruction cache locality and branch prediction efficiency along a relatively small number of hot code paths. However, these optimizations require continuous profiling and rebuilding of applications to ensure that the code layout matches the collected profiles. If an application’s code is frequently updated, it becomes challenging to map profiling data from a previous version onto the latest version, leading to ignored profiling data and missed optimization opportunities.
In this paper, we propose OCOLOS, the first online code layout optimization system for unmodified applications written in unmanaged languages. OCOLOS allows profile-guided optimization to be performed on a running process, instead of being performed offline and requiring the application to be relaunched. By running online, profile data is always relevant to the current execution and always maps perfectly to the running code. OCOLOS demonstrates how to achieve robust online code replacement in complex multithreaded applications like MySQL and MongoDB, without requiring any application changes. Our experiments show that OCOLOS can accelerate MySQL by up to 1.41×, the Verilator hardware simulator by up to 2.20×, and a build of the Clang compiler by up to 1.14×.
Talks
- RPG2: Robust Profile-Guided Runtime Prefetch Generation.
ASPLOS, San Diego, CA, May 2024 - OCOLOS: Online Code Layout OptimizationS.
MICRO, Chicago, IL, Oct. 2022
Honors & Awards
- Paper selected for IEEE Micro Top Picks in Computer Architecture from 2023
- Outstanding Graduates Awards
Awarded by Harbin Institute of Technology for overall academic excellence at graduation - Fuji Xerox Scholarship
Awarded for ranking 1st in undergraduate GPA for one academic year - Suzhou Industrial Park Scholarship
Awarded for ranking 2nd in undergraduate GPA for one academic year
Professional Service
- Journal reviewer for IEEE Transactions on Computers (TC), 2023
Teaching
- Teaching Assistant: CIS505 Software Systems (distributed systems), Fall 2020, Fall 2021
Miscellaneous
- I enjoy writing fan fictions, and my self-published fan fictions have been sold more than 1,100 copies in China.
- I studied Japanese in the UPenn’s Japanese Language Program. I’ve passed the JLPT N3, and am aiming to pass the N2.
- I had been learning Chinese dance for 7 years and playing the piano for 5 years, and received certificates from Beijing Dance Academy and Central Conservatory of Music.
 CmdLine
Blog★
 Nextcloud
Storage
 masto-cli★
 Retainic★
 LinguaFlow★
